How to Structure Game Server Builds: Branch Management Best Practices

Branch management is one of those practices that is well understood inside large studios and almost entirely undocumented everywhere else. Teams who have it rarely write it down, because it was built once and then became invisible. Teams who do not have it usually find out at an inconvenient moment.
This article puts the common practice in one place:
The first half covers the handful of concepts worth understanding before you build anything.
The second half describes three concrete structures at different levels of available resources: one for a solo developer, one for a working team, and one for a studio with a formal release process.
Three rather than one, because the right structure depends on how much engineering time you can spend on it. A process designed for a fifty-person studio will be quietly abandoned by a team of three. There is no single correct answer here, and over-engineering this early carries a real cost. The structure that works is the one your team will actually follow.
What Branch Management Means
Strip away the tooling and the problem reduces to three pieces.
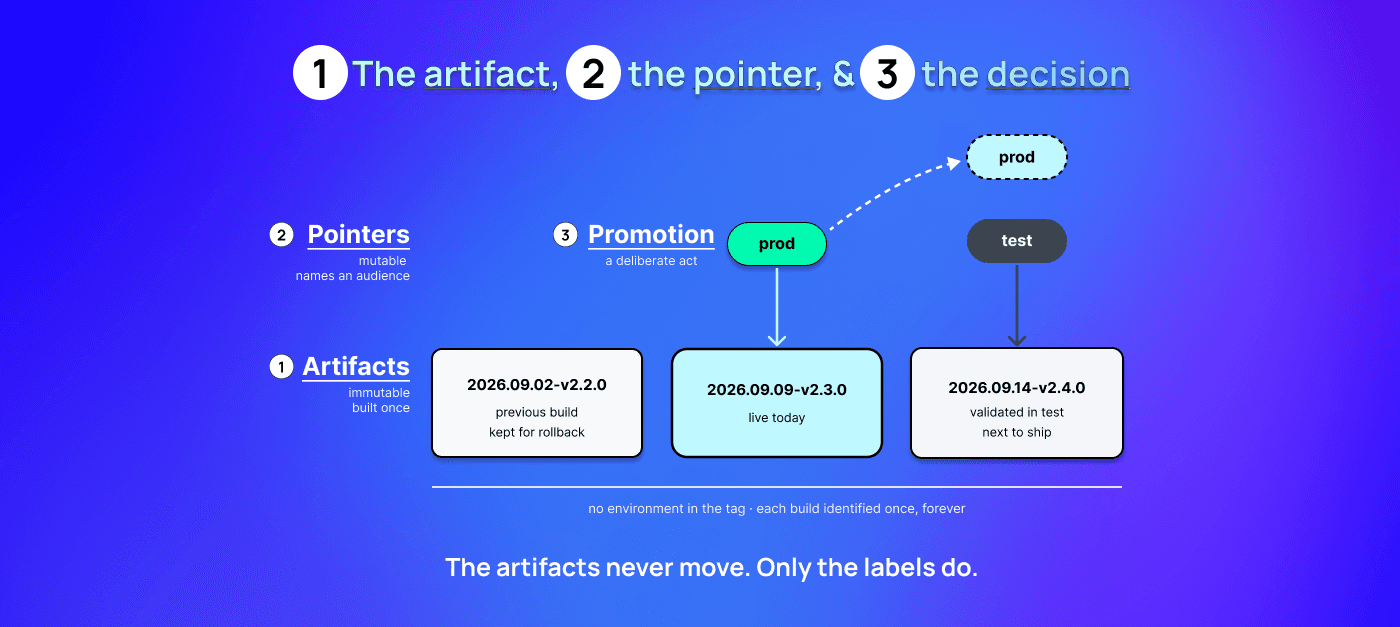
An artifact is a built server image. Once it exists, it never changes.
A pointer is a name saying which artifact is current for a given audience. "Production" is a pointer, not a thing.
A decision is the act of moving a pointer from one artifact to another.
Everything else is tooling wrapped around those three.
Some platforms hand you named branches and a promote button. Others hand you versions and let you decide what the names mean. Either way you are assembling the same three pieces, and the approaches below differ mainly in how much ceremony surrounds the third one.
One distinction does most of the work here: The artifact is immutable; the pointer is not. Most release accidents come from confusing the two.
Concepts Worth Knowing Before You Pick
One build, several destinations
The same image that runs in testing is the image that should run in production.
Not a rebuild from the same commit, not a recompile with different flags, the same bytes. Rebuilding per destination introduces a gap between what was validated and what shipped, and that gap is invisible until something depends on it. Teams converge on this early, because the alternative is a bug class that reproduces nowhere except in front of players.
Tag uniqueness
A tag that gets reused stops being an identifier and becomes a label.
"We deployed v2.3" is a precise statement right up until someone pushes a different image under the same tag, at which point it describes two builds depending on when you ask. Attaching something unique to every tag, a build number or a commit hash, preserves the ability to answer that question later. It costs nothing at build time and is difficult to retrofit.
One detail here is easy to get wrong. A tag like prod-2026.09.14-v2.3.0 reads sensibly, but it puts the destination inside the identifier, which means the build QA approved is not the build that ships. Keeping the environment out of the tag (2026.09.14-v2.3.0) and in the pointer instead is what makes promotion possible without rebuilding.
Pointers and what they point at
Once the artifact is fixed, you need something mutable to say which one is live.
That is the pointer, and on most platforms it is a named version, a branch, or a config value your matchmaker reads. Its whole job is to be changeable, cheaply and reversibly, which is what makes the next two concepts work.
How things move forward
Nothing should escalate from testing to production on a timer, on a merge, or as a side effect of something else.
Promotion works best as its own action, separate from building and from deploying, because that separation is what lets a person or a check stand between a build and its players. Teams differ on who performs it. They mostly agree it should be one identifiable act rather than an emergent property of the pipeline.
Going back to a previous build
Rolling back means putting players on the build that was live before. How fast that happens depends on a choice made earlier: whether the previous artifact still exists somewhere reachable.
If it does, rolling back is the same pointer change as promoting, run in reverse. Seconds, and nothing new can break. If it does not, the path back runs through a build job, which takes as long as a build takes and can fail in its own ways. The difference is not tooling or skill. It is whether the old build was kept.
Keeping a handful of recent builds around costs registry space. Most teams find that cheaper than the alternative.
Where configuration lives
Some settings differ between testing and production: which regions to run in, which database to talk to, which keys to use. Those values can either be baked into the build or handed to it when it starts.
Baked in, the test build and the production build are two different builds, and “one build, several destinations” quietly stops being true. Handed in at startup, usually as environment variables, a single build stays valid everywhere.
The takeaway is narrow. If you find yourself building twice because two environments need different settings, the settings are in the wrong place.
Cold builds and cache windows
Platforms that distribute builds worldwide keep recently used ones ready to run, and let unused ones fall out of that ready state. A build nobody has deployed in a while may need to be fetched again before it can start, which adds time to the first deployment after a quiet stretch.
That matters most for rollback, because the build you want back is by definition one you stopped deploying. On Edgegap, cached images expire after 72 consecutive hours without a deployment, so a build left idle over a long weekend is cold by Monday.
Teams who care about rollback speed either deploy the previous build occasionally to keep it ready, or accept the delay and plan around it. Both are reasonable. The one that hurts is not knowing which you picked.
Three more are worth naming without dwelling on. Client builds and server versions move together, so a promotion is also a compatibility decision. Registry cleanup needs a floor as well as a ceiling, because "delete everything older than 30 days" eventually deletes the thing you wanted to roll back to. And what you actually want after an incident is narrow: which image, promoted by whom, when.
Approach 1: Two Versions and a Rule
For solo developers and teams of two or three, where the release decision happens inside one person's head.
At this size the bottleneck is not coordination, it is remembering. There is no QA team to sign off and no second engineer to catch a mistake, so the structure has to be small enough that skipping it is harder than following it. Two versions is about as small as a structure gets while still being one.
Tags 2026.09.14-1, 2026.09.14-2, 2026.09.15-1
Pointers test -> 2026.09.15-1
prod -> 2026.09.14-2
Key Suggestion | Taking Action |
|---|---|
Keep exactly two versions. |
|
Every build takes a tag never used before. A date and a counter is enough. | The point is not elegance, it is that a tag can never be ambiguous six weeks later. |
Deploying a build to yourself means pointing | Shipping it means pointing |
Rollback is the same move in reverse, which only works if you can remember the previous tag. | Write it down. One line in a text file in the repo, updated on every promotion, is unglamorous and sufficient. |
Clean up once a month by hand. | Delete old tags, leave anything a pointer currently references. |
What this prevents is the specific failure of an unreviewed build reaching players.
What it does not give you is any record of why a promotion happened or what changed.
At three people that is usually fine, because you can just ask. It stops working roughly when the answer to "who promoted this?" is no longer obvious.
Setup should take under an hour. Ongoing cost is a minute or two per release.
Approach 2: CI Owns Staging, a Person Owns Production
For teams at studios of roughly five to thirty, where builds outpace any one person's attention.
Once builds happen faster than anyone tracks them, the useful split is not more environments. The preferable split is between what gets automated and what stays manual. Automating everything up to production removes the tedium. Leaving the last step manual keeps a person in the loop at the one point where being wrong is expensive. That asymmetry is the idea, and most of the structure below exists to support it.
Tags v1.4.2-a91c3f (semver + short commit hash, produced by CI)
Pointers dev -> built on every push to a feature branch
staging -> updated automatically on merge to main
prod -> updated only by a manually triggered CI job
Key Suggestion | Header 2 |
|---|---|
Tags come from CI, never from a person | The version number tells a human what changed. The hash makes the build reproducible from the tag alone, which matters more than it sounds like it should. |
Merging to main updates | Production is updated by a separate, manually triggered job that takes a tag as input and writes it onto the |
Worth knowing about the platform layer here. | On Edgegap, app versions are mutable, so updating
|
Cleanup becomes a scheduled job rather than a monthly chore | The shape most teams want is "delete versions older than thirty days, never fewer than the last ten, and never anything a live deployment references." Edgegap has no retention-policy engine today, so this is written against the API rather than configured. Roughly an afternoon of work, and the exclusion rule is the part worth care. |
Client builds and server versions still move together | Teams this size usually keep the previous prod version deployable for a window after promotion, so players on a stale client are not stranded mid-session. |
What this buys is that nobody has to remember anything, and the record of what shipped exists without anyone maintaining it.
What it still does not do is prevent a promotion that should not have happened. There is a person in the loop, and people approve things.
Setup should take roughly a day of a backend engineer. Ongoing cost is close to zero.
Approach 3: Auditable Promotion
For studios with live-ops, compliance requirements, or a release process that predates the infrastructure decision.
At this scale the release process usually already exists, defined by people who do not work on infrastructure, and the platform's job is to fit inside it rather than replace it. That changes the design question. The goal is no longer keeping the process light, it is making every step inspectable, because someone will eventually ask what shipped, when, and on whose approval, and "I remember" does not survive the question.
Tags v1.4.2-a91c3f (human-readable alias)
Identity sha256:9f2c... (what deployments actually pin to)
Pointers staging -> digest
prod-canary -> digest
prod -> digest, changed only by a reviewed, merged commit
Key Suggestion | Taking Action |
|---|---|
Digests over tags | A tag is a label a human chose, and humans can move labels. A digest is a content hash and cannot be moved. Studios pinning deployments to digests treat tags purely as human-readable aliases. This is the single largest jump in rigor available, and it costs nothing beyond a change in what CI records. |
Versions declared as code | Managing versions through Terraform or the API rather than a dashboard turns a promotion into a reviewed, merged change with an author, a timestamp, and a diff. The studio's existing approval process then applies automatically, because the promotion is a pull request like anything else. Both paths exist on Edgegap, and this is the tier where that matters most. For the layer underneath, Edgegap's guide on hosting scalable game servers with Docker or Kubernetes covers how the containers themselves get built and run. |
Gates before the pointer moves | A soak test, a load benchmark, a QA sign-off recorded somewhere machine-readable. The distinction that matters is between a process people follow and a process the pipeline enforces. The second one survives a bad week. |
Canary | A separate pointer taking a small slice of real traffic before full promotion. Be clear-eyed about what it involves: routing players to a specific server version is something studios build in their own matchmaking or session layer today, not something orchestration platforms generally hand you. A separate version, a routing rule you own, and an observation window with an agreed definition of clean. |
Signing and provenance | Images signed at build, signatures verified at promotion, promotion refused when verification fails. This is increasingly a compliance requirement rather than a nicety, particularly for studios shipping on console. |
Retention | Automated pruning as in Approach 2, with a hard rule that nothing referenced by a live or canary pointer is ever a deletion candidate, and with the deletion itself logged. |
All of this is buildable on any platform that exposes versions and an API, and none of it is buildable without clear guidelines and a working knowledge of the studio’s internal process.
How long it takes depends entirely on what that process already looks like.
Choosing Between Them
The useful signal is not team size directly. It is how often the answer to "who promoted this, and why" requires asking someone.
When the answer is obvious because there are three of you, Approach 1 is not a compromise, it is correct. When you find yourself asking, Approach 2 pays for itself in about a month. When someone outside the engineering team needs the answer, you are already in Approach 3 territory whether or not you have built it.
There is a trade-off underneath all of this worth stating plainly. A platform that hands you one opinionated pipeline saves you this decision and costs you the ability to make it differently. A platform that hands you versions and an API asks you to choose, which is only a burden if nobody chooses. Most teams unhappy with either arrangement got there by default rather than by decision.
Pick one deliberately, and like anything in software development, expect to iterate on it once, either at scale or once the process solidifies. A clear first structure is what makes the second one easier to build.
Written by
Jakub Motyl (Product), and Gabriel Parent (Director)